User guide5 min
Add a site
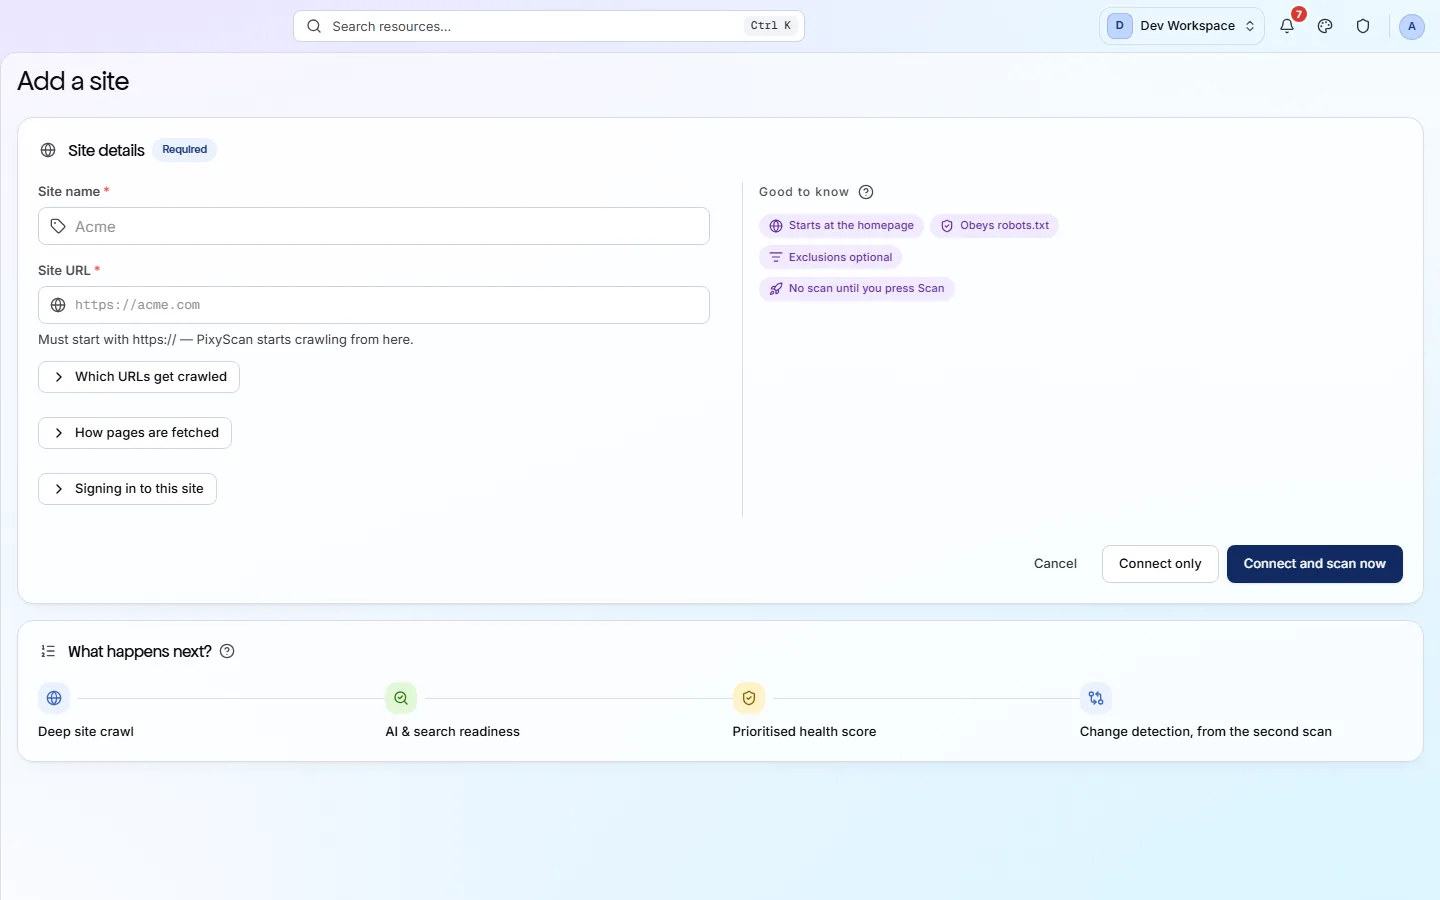
A site is one domain you want watched. Give it a name, paste its URL and press Connect and scan now. The three optional sections are there for sites that need them - most do not.
The two required fields#
A name for you, and a URL for the crawler.
- 1
Open Add a site
The button at the top of the workspace sidebar, on every screen.
- 2
Give the site a name
Whatever you will recognise in a list: a brand, a client, an environment. It is only a label, and you can change it later.
- 3
Paste the site URL
It must start with https://. This is where the crawl begins, so use the address visitors actually land on, including www if that is your canonical form.
- 4
Press Connect and scan now
The site is created and the first crawl starts straight away. Connect only creates the site without scanning it, which is what you want if you are still setting up crawl rules.
app.pixyscan.com/w/…/s/new
Which URLs get crawled#
Where the crawler may go, how deep, and how many pages it may fetch.
Open this section if part of your site should be left alone, or if it generates endless URLs: product filters, a calendar, an internal search. Otherwise the defaults are fine.
| Field | Default | What it does |
|---|---|---|
| Include patterns | — | Leave empty to crawl the whole domain. Add one and only matching URLs are crawled. |
| Exclude patterns | — | URLs the crawler must skip, such as an admin area or a print view. Empty by default. |
| Match mode | Required with patterns | Pre skips a URL before fetching it, which costs nothing. Post fetches it and discards it afterwards, which still records that the URL exists. |
| Max pages | Your plan's cap | The most URLs one scan may fetch, between 1 and 50,000. This is also your spending limit - see the note below. |
| Max depth | — | How many links from the homepage the crawler may travel. Empty means no limit, which suits most sites. |
| Read the sitemap | On | Follows sitemap.xml if you have one, which finds pages nothing links to. Leave it on. |
| Obey robots.txt | On | The crawler follows your robots rules. Turn it off only for a staging site that blocks everything on purpose. |
One crawled URL is one credit
How pages are fetched#
Which engine reads the page, what the crawler calls itself, and how fast it goes.
| Field | Default | What it does |
|---|---|---|
| Engine | HTML | Reads the HTML your server sends, which is what a search crawler sees first. The alternative runs your JavaScript in a real browser first: about seven times slower, and Pro only. |
| User agent | PixyScan | What the crawler calls itself. Change it only if your firewall or CDN needs a specific string allowed through. |
| Crawl speed | Moderate | How hard the crawler hits your server. Slower is gentler on a small host and takes longer; the form shows the effect on run time. |
Leave the engine on HTML for the first scan
Signing in to this site#
For a staging site behind HTTP basic auth.
A username and a password, sent with every request. This is the only sign-in this form supports. A site behind a login form, single sign-on or an IP allowlist cannot be crawled.
Custom request headers are available too, but on the site's Crawl settings once it exists - not on this form.
What happens after you press Connect#
Four stages. The fourth starts on your second scan.
| Field | Stage | What it does |
|---|---|---|
| Deep site crawl | 1 | Finds your pages and assets, and records the status code each one returns. |
| AI & search readiness | 2 | Scores how easily search crawlers and AI answer engines can read and quote each page. |
| Prioritised health score | 3 | Classifies findings into Critical, Important and Standard issues. |
| Change detection | 4 | From the second scan onwards, each run is compared with the previous one, so you see what a release changed instead of the whole list again. |
If the product does not match this page, the page is wrong and we would like to know. Tell us