Make sure search engines can reach your pages
Crawlability is whether search engines and AI bots can find and reach your pages. This feature shows your robots.txt rules, your sitemaps, your redirects and anything that keeps bots out.
- AI bots, allowed or blocked
- 18
- AI bots, allowed or blocked
- steps in the crawler journey
- 4
- steps in the crawler journey
- full weight in your score
- 1×
- full weight in your score
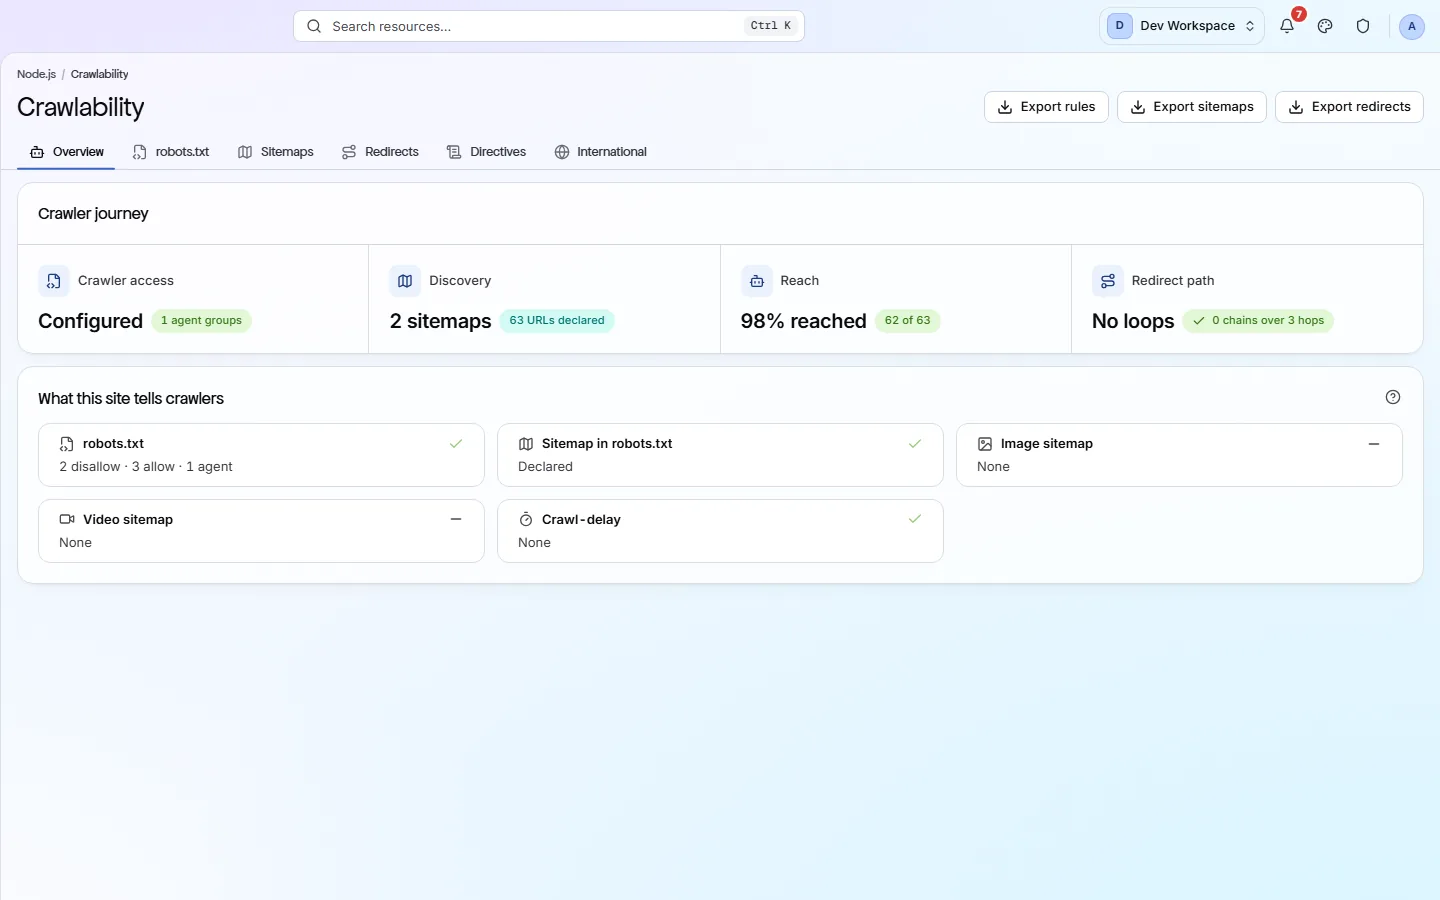
The crawler journey
Four steps every search engine takes on your site
The overview walks through them in order. A problem at any step means pages go unseen.
1 · Crawler access
Your robots.txt, the file that tells bots what to skip. Shown rule by rule, with which AI bots it allows or blocks.
2 · Discovery
Your sitemaps, the lists of pages you want found. Each file shows how many URLs it lists.
3 · Reach
How many sitemap URLs the scan actually reached. Below 90% is marked as a warning.
4 · Redirect path
Redirect chains, loops and redirects to other sites, which slow bots down or stop them.
What it finds
Crawl problems and their fixes
These checks count in full in your score, because a page that cannot be found cannot rank.
- Critical
No XML sitemap found
Search engines find new and deep pages much more slowly without one.
How to fix: Publish
/sitemap.xmlreturning a 200 status, and list it in robots.txt. - Critical
Pages have no canonical tag
When a page has several addresses, search engines have to guess which is the main one.
How to fix: Give every indexable page one full-address
<link rel="canonical">, usually pointing at itself. - Important
No robots.txt file
Bots have no rules to follow and no pointer to your sitemap.
How to fix: Serve
/robots.txtwith a 200 status. To keep a page out of search, use a noindex tag, not robots.txt. - Important
robots.txt does not point to the sitemap
It is the first file bots read, and the easiest place for them to find your sitemap.
How to fix: Add a line such as
Sitemap: https://example.com/sitemap.xmlto robots.txt. - Important
The sitemap lists pages robots.txt blocks
The two files contradict each other, so bots are told to visit and not to visit.
How to fix: Decide which is right: remove those URLs from the sitemap, or lift the Disallow rule.
- Standard
The sitemap lists pages that do not load
Search engines waste their visit on redirects and errors, and trust the sitemap less.
How to fix: List only live pages at their final address. Remove or update the rest.
Inside the app
Every file that guides a crawler
The crawler journey in four steps, above your site's crawl settings.
Click around: it is a working copy of the screen, filled with our test site's data.
Your health score
The checks that count the most
Crawlability and Indexability are the only categories counted at full weight. If search engines cannot reach or index a page, nothing else about it matters.
How the score works- Crawlability weight
- 1×
- Crawlability weight
- Indexability weight
- 1×
- Indexability weight
- crawlability checks
- 18
- crawlability checks
- indexability checks
- 24
- indexability checks
Your first visit
Check your crawlability in four steps
- 1
Read the crawler journey and start with any step marked Missing or showing loops.
- 2
Open robots.txt and check the
User-agent: *group and the AI bot grid. - 3
Open Sitemaps and compare URLs listed with URLs reached.
- 4
Open Directives and choose Canonical faults to find broken canonicals.
The checks behind this screen
Check categories shown here
These groups of checks feed the numbers on this screen. Each one is explained on the score page.
On-Page
35 checksThese checks look at each page's title, meta description, headings and URL. They flag any that are missing, empty, duplicated on other pages, too long or too short, including pages with more than one H1, because these are the first things search engines read and show.
Crawlability
18 checksYour robots.txt file and your sitemaps tell search engines which pages to visit. These checks read both, and they flag sitemaps that list broken, blocked or duplicate pages, CSS and JavaScript files that robots.txt blocks, and pages that failed to load during the scan.
Indexability
24 checksA page can be reachable and still be kept out of search results. These checks look at canonical tags, noindex and nofollow rules, pagination and soft 404s (error pages that report success) to show which pages search engines may index. They also catch canonicals that point at broken, redirected or noindexed pages, or that contradict each other.
International
7 checkshreflang tags tell search engines which language or region each version of a page is for. These checks make sure the tags point back at each other in pairs and use valid language codes.
What this screen is for
The results it is part of
A screen is where you look. These are the things PixyScan does for your site that you see here.
FAQ
Common questions about this feature
Does PixyScan follow my robots.txt?
Yes, by default. It reads your robots.txt first and skips blocked pages, like a well-behaved search engine. You can turn this off in Settings, Crawl tab, for example to check a staging site.
Why is Reach low when my sitemap is fine?
The scan stops at your page limit per scan: 500 on Free, 5,000 on Hobby, 10,000 on Basic, 15,000 on Pro. A 20,000-URL sitemap on Hobby will always show low reach. Exclude patterns can also skip sitemap URLs.
Can I download these lists?
Yes, from Hobby up. Export rules, Export sitemaps and Export redirects sit at the top. Directives and International have their own export buttons.
Continue the product tour
Previous and next features
Features follow the order of the app’s menu. See the full list to jump to any of them.
See what is wrong with your site
Add your site and get your score, your to-do list and a fix guide for every problem. Free for one site and 500 pages a month, with no time limit.
Nothing to install · Cancel any time